
Models & Providers
dsh-model-manager-ansonfis
Ansonfishing/dsh-model-manager · ★ 0
 Ansonfishing
DSH plugin: manage local model inference servers (llama.cpp / vLLM / SGLang) — registry, safe start/stop, parameter profile versioning with validation.
Manifest details
安装
dsh plugin --profile web add 'github:Ansonfishing/dsh-model-manager#d9c6b17c2a71528bbdd3faf9b7eb506cb7854dff'GitHub 源码安装:首次需按提示配置 allowBuilds 构建授权后重试
For install and environment setup, plus plugin development tutorials, see DSH community docs ↗
README
Table of contents
A control panel for your local LLM inference servers — a plugin for DSH (DeepSeek Harness).
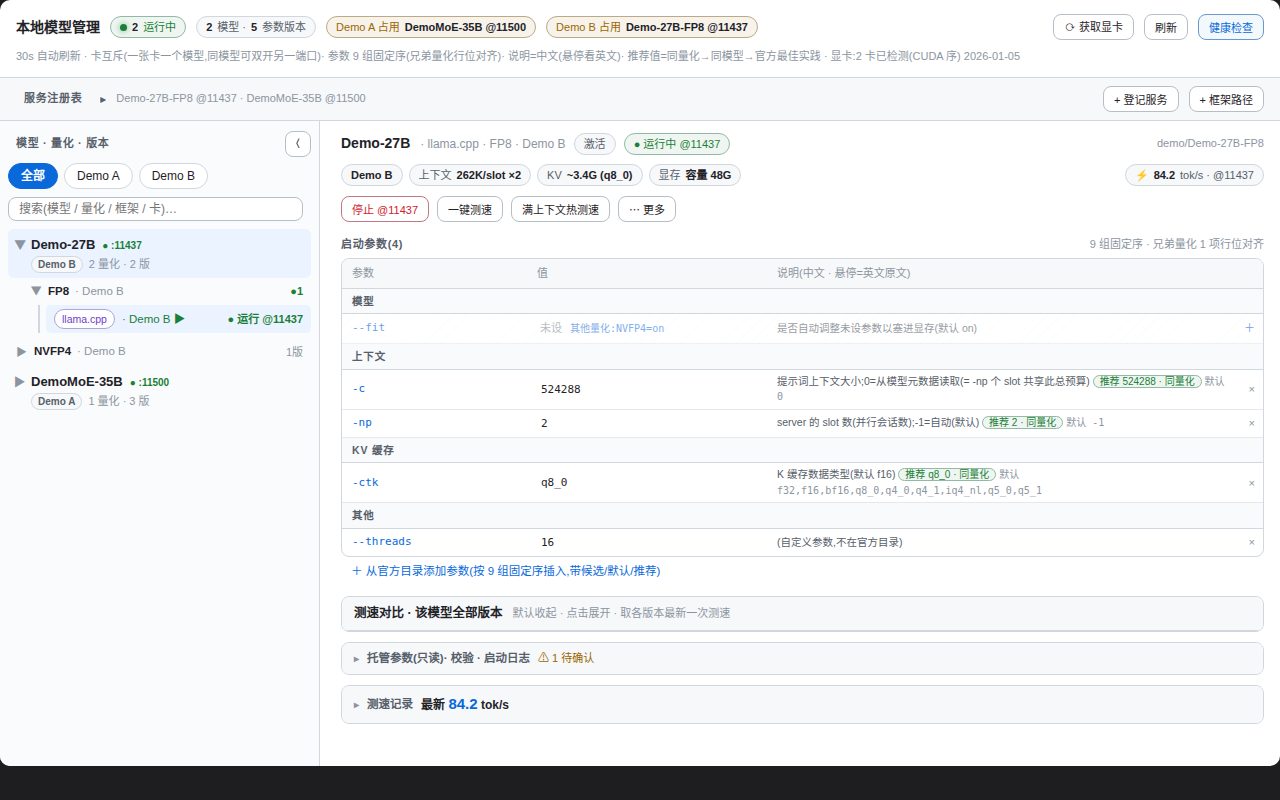
Why
Run a couple of local inference servers (llama.cpp / SGLang / vLLM) and the parameter knowledge scatters across terminal history and notes: which -c / -np does this model want? Does the VRAM actually fit? Which framework boots on this card?
With this plugin, the answers live in one panel:
- Before: digging through shell history, hand-calculating KV memory, learning about over-budget configs from an OOM.
- After: a service registry that shows who runs on which card in real time, parameter profiles validated for VRAM before you save, one-click tok/s benchmarks.
Quick start
Prerequisites: DSH (with web) + pnpm; GPU detection needs python3 (falls back to nvidia-smi when missing).
cd ~/.dsh/profiles/web                      # your DSH web profile directory
pnpm add github:Ansonfishing/dsh-model-manager
Then add "dsh-model-manager" to the dsh.profile.bundles array in package.json and restart dsh. A "Model Manager" tab appears in the conversation view — done.
Features
- Service registry — register local inference servers (port, framework, model, GPU) with live health checks and one-click stop.
- Parameter profiles — named parameter versions per "model × framework × GPU" for llama.cpp / SGLang / vLLM. Rows follow a fixed 9-group order (model → context → KV → speculative decoding → sampling → performance → parallelism → server → misc); different quantizations of the same model × framework share one union row set with aligned rows — flags unset in the current version show as grey "other quant: value" rows, so cross-quant differences pop out. Recommended values resolve through a 3-tier provenance chain (same-quant live value → sibling quant → official best practice), labelled per cell; nothing is guessed.
- GPU detection — auto-enumerates cards (
libcudaprimary,nvidia-smifallback); card index = theCUDA_VISIBLE_DEVICESvalue. - VRAM validation — estimates KV memory from
-c/-npwhen you save a profile and warns immediately if the target card can't hold it. - One-click benchmark — sends a fixed prompt (non-streaming, 256 tokens) to a running server and records tok/s; a full-context hot benchmark additionally verifies the usable context is at least the target, then runs streaming warmup + measurement (TTFB / prefill / decode).
- Safety rails — never uses
pkill; stopping an external service requires explicit force plus a two-click confirmation in the panel; stopping port 11437 (DSH's own inference port) additionally warns that it will interrupt the current session.
No DSH? Take a look anyway
Clone this repo and open test/harness/index.html in a browser — a zero-dependency render harness that shows the full panel with mock data; ?chrome=0 hides the harness bar.
Local GPU table (optional)
The repo ships no hardcoded GPU mappings. To show card names and memory capacity, create ~/.dsh/model-manager/builtin-gpus.local.json:
{
  "0": { "name": "RTX 4090", "memGb": 24 },
  "1": { "name": "RTX 6000 Ada", "memGb": 48 }
}
Without the file the panel falls back to "GPU 0 / GPU 1" and skips VRAM validation.
Development
npm test                          # node --test test/*.test.mjs
node build/build-client.cjs       # rebuild lib/client.js from mockup-v3.html
Local development: after cloning, use pnpm add link:../path/to/dsh-model-manager in your profile. Client-only changes need a browser refresh; Node-side changes (index.js / lib/*.js) need a dsh restart.
Architecture at a glance
| Layer | File | Responsibility |
|---|---|---|
| Entry | index.js |
registers 14 tools + 17 same-origin routes |
| Lifecycle | lib/lifecycle.js |
registry CRUD, health probes, managed start/stop |
| Safety | lib/safety.js |
stop policy (fuser/kill), protected ports |
| Validation | lib/validate.js |
launchCommand parsing + rule engine |
| GPU | lib/gpu.js |
detection + local GPU table loading |
| Adapters | lib/adapters/*.js |
llama / sglang / vllm command assembly |
| Client | lib/client.js |
single-file React component (built from the mockup) |
License
MIT © Ansonfishing
Related plugins
dsh-plugin-reasonix
 esengine
/DeepSeek-Reasonix/integrations/dsh-plugin
把 Reasonix 作为 dsh 子智能体接入:一层配置补丁让 subagent-acp 提供方启动 reasonix acp,并以 reasonix 工具暴露给模型。纯配置、无代码、不在 npm;接入的是子智能体,不是模型服务商。
dsh plugin --profile web add 'github:esengine/DeepSeek-Reasonix#af0e954f5629492980718fc0e36030fec0abc682&path:/integrations/dsh-plugin'dsh-purge
 YuJunZhiXue
/dsh-purge
DeepSeek Harness 破甲:让所有模型都能破甲,不同模型可换不同提示词;默认提示词面向国模「小码酱」。Jailbreak for every model — swap prompts per model. 求 Star 收藏 ⭐ 如要二开,请查看署名要求部分
dsh-purge-mmparko
 mmparko
/dsh-purge
DeepSeek Harness 破甲:让所有模型都能破甲,不同模型可换不同提示词;默认提示词面向国模「小码酱」。Jailbreak for every model — swap prompts per model. 求 Star 收藏 ⭐ 如要二开,请查看署名要求部分
dsh plugin --profile web add 'github:mmparko/dsh-purge#033e6bd1e0f101352b39075ecd0d758ffef26b76'dsh-connect-workbuddy
 dingminhua
/dsh-connect-workbuddy
把本机登录的 WorkBuddy 模型(国内版与国际版)接入 DeepSeek Harness:每次刷新按上游目录自动读取每个模型的积分倍率,支持逐模型图片输入开关、多账号切换与账号池自动换号,并提供每日签到、卡片与输入框里的胶囊积分读数等只读积分概览。
dsh plugin --profile web add 'dsh-connect-workbuddy@5.15.0'dsh-image-gen
 shanliuling
/dsh-image-gen
让 DeepSeek Harness 像 ChatGPT 一样,在对话里直接生成图片。
dsh plugin --profile web add github:shanliuling/dsh-image-genagent-vision-toolkit
 Anionex
/agent-vision-toolkit
为纯文本模型"看图“设计更好的视觉工具箱和技能,支持多图理解,图片问答,前端UI还原、GUI 自动化等,并可选无缝接入多个主流agent,直接识别粘贴图片| A vision toolkit and skill designed for text-only llms — image Q&A, long-screenshot OCR, frontend UI restoration, and GUI automation, with optional seamless integration for Codex, Claude Code, Pi, Oh My Pi, and OpenCode
dsh plugin --profile web add github:Anionex/agent-vision-toolkit